Xiaomi MiMo-V2.6
Xiaomi's September 2026 omni-modal reasoning series — a trillion-parameter flagship (Pro), a low-cost workhorse (Flash), and a latency-tuned UltraSpeed variant, all three sharing a roughly million-token context and reachable through a standard API or, for Pro and Flash, open MIT-licensed weights.
Last verified · 2026-10-23 · by Moe Ameen
Published 2026-09-21 · Updated
Short answer
Xiaomi MiMo-V2.6 is a September 2026 series of three omni-modal language models: Pro, a flagship of over a trillion parameters; Flash, a 309-billion-parameter mixture-of-experts model; and Pro-UltraSpeed, a fast-serving edition of Pro. All three read text, images, audio, and video, output text, and hold about a million tokens of context. Pro and Flash weights are open under MIT.
Key takeaways
- MiMo-V2.6 has three models: Pro (1T+ parameters), Flash (309B MoE), and Pro-UltraSpeed.
- They take text, image, audio, and video input and output text.
- Each has a context window of about one million tokens.
- Pro and Flash weights are on Hugging Face under the MIT license.
- It writes text. Clips, carousels, and published posts need a tool like Kompozy.
What is Xiaomi MiMo-V2.6?
Xiaomi MiMo-V2.6 is the September 2026 release in Xiaomi's MiMo family of large language models. V2.6 is a three-model series, not a single model. MiMo-V2.6-Pro is Xiaomi's flagship, built at a scale of over a trillion parameters for the most demanding, long-horizon work. MiMo-V2.6-Flash is a smaller open-source Mixture-of-Experts model with 309 billion total parameters and 15 billion active per token. MiMo-V2.6-Pro-UltraSpeed is the fast-serving edition of Pro, built from the same checkpoint and matched to it in quality.
The common thread is "omni-modal" input: the models read text, images, audio, and video rather than text alone, and they output text. Every model in the series has a context window of roughly one million tokens, enough to hold an entire book, a long webinar transcript, or a large research corpus in a single prompt.
You can reach MiMo-V2.6 through gateways such as OpenRouter, using a standard chat-completions interface with tool use and structured output. Licensing is open this generation: Xiaomi published both MiMo-V2.6-Pro (Pro-RL) and MiMo-V2.6-Flash (Flash-RL) as open weights on Hugging Face under an MIT license, which permits commercial use and self-hosting, including the trillion-parameter flagship.
Pro-UltraSpeed is a hosted fast-serving mode built on the same Pro checkpoint rather than a separately downloadable model. Because the series just launched, treat exact per-model pricing and benchmark specifics as still settling — confirm the current details on Xiaomi's official MiMo pages before relying on them.
What can you make with MiMo-V2.6?
- Summaries and structured analysis of long source material — transcripts, PDFs, research, or comment threads — reasoned over in a single large-context prompt
- Notes and outlines pulled directly from audio or video, since the model ingests recordings without a separate transcription step
- Drafted text: outlines, long-form copy, rewrites, extraction of key points and quotes from a big input
- Answers, classifications, and tool-calling outputs for an app, agent, or automation built on the API
- Structured (JSON) output for pipelines that need machine-readable results
- Note: it outputs text and analysis — it does not produce captioned clips, carousels, persona video, images, blogs formatted for publishing, or anything scheduled to a platform
Where does MiMo-V2.6 fit in a content pipeline?
Think of MiMo-V2.6 as the reader in the room: hand it a two-hour webinar, a research folder, or a stack of customer calls and it will reason across the whole thing and hand back the sharpest ideas — because its omni-modal input and roughly million-token context let it hold the entire source at once. What it will not do is turn those ideas into content anyone sees. It writes tokens; it does not caption a clip, size a carousel to each platform, keep a persona's face consistent across images, or publish. Kompozy is the studio and the distribution that pick up exactly there.
The concrete pipeline: use MiMo to ingest and reason over the raw source, then bring that same source into Kompozy and set a Persona Brief so voice, terminology, and banned words govern every output. From one input Kompozy generates the formats MiMo can't — Clipped Shorts cut from the long video at its strongest moments, captioned Persona Shorts and brand-exact Persona Frames fronted by a face-locked avatar, listicle-style concept video, brand-exact Carousel Posts, Photo Posts, Quote Graphics, a Blog Article, and an Email Newsletter.
Then Autopilot schedules and publishes the whole set across the eight social platforms plus blog and email, each piece behind a per-post review gate.
- Use MiMo-V2.6 to read and reason over a large or multimodal source — a long webinar, a research corpus, a batch of calls or a screen recording — and pull the strongest angles.
- Bring that same source into Kompozy and set a Persona Brief so your voice, terminology, and banned words carry across every output.
- Fan the one source into finished formats: Clipped Shorts, a captioned persona or avatar video, listicle-style concept video, brand-exact carousels, photo posts, quote graphics, a blog, and a newsletter.
- Review the batch in the per-post queue and let Kompozy reframe each clip and post for TikTok, Reels, Shorts, X, LinkedIn, and the rest.
- Let Autopilot schedule and publish across the eight social platforms plus blog and email.
What does this look like in Kompozy?
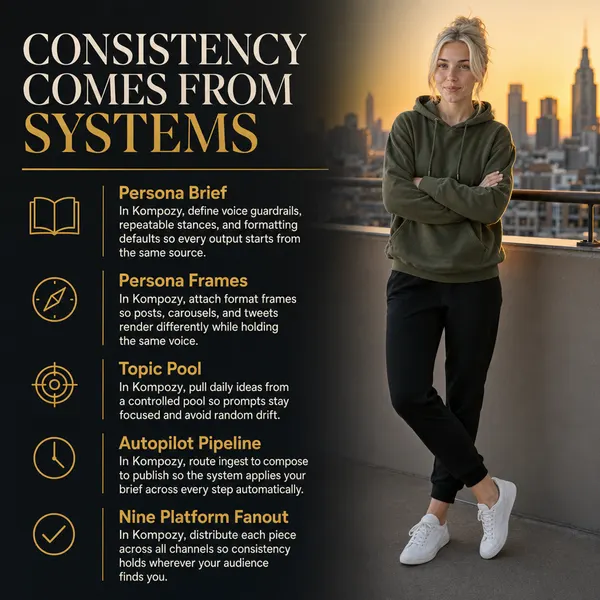
A Persona infographic generated in Kompozy. It shows the format; MiMo was not used to make it.
Who is this for, and who should skip it?
Best for:
- Developers who want an open-weight model that reads audio and video directly
- Teams reasoning over long transcripts, recordings, or document sets in one prompt
- Builders who need tool use and structured output through OpenRouter
Not ideal for:
- Anyone who needs video, images, captions, or publishing
- Teams without the hardware to self-host a trillion-parameter model, unless they use an API
- Buyers who need settled pricing and benchmarks, which are still moving
Frequently asked questions
What is Xiaomi MiMo-V2.6?
It is the September 2026 release in Xiaomi's MiMo family of large language models — a three-model series: Pro (a trillion-parameter flagship reasoning model), Flash (a smaller open-source model), and Pro-UltraSpeed (a fast-serving edition of Pro). All three are omni-modal, taking in text, images, audio, and video.
Can MiMo-V2.6 make social media posts or video?
Not directly. MiMo is a language model — it reasons and drafts text, and reads images, audio, and video, but it does not caption clips, build carousels, generate persona video, keep a face consistent, or publish. To turn its output into finished, scheduled posts across platforms, pair it with a content engine like Kompozy.
What can MiMo-V2.6 ingest?
It is omni-modal, so it accepts text, images, audio, and video as input. That means a podcast episode or a screen recording can be a direct source without a separate transcription step, and its roughly million-token context — shared across Pro, Flash, and UltraSpeed — can hold a full transcript or a large document set in one prompt.
How do I get MiMo-V2.6 output published across platforms?
Use MiMo for the ingestion and reasoning step, then run the same source through Kompozy: set a Persona Brief for your voice, let it generate Clipped Shorts, persona/avatar video, carousels, photo posts, quote graphics, a blog, and a newsletter, and let Autopilot schedule and publish across the eight social platforms plus blog and email.
How do we know this?
We checked every figure and vendor claim on this page against the sources listed below on 2026-10-23, including model sizes, modalities, context windows and supported parameters in OpenRouter's model listings and the MIT license on Hugging Face; we removed history, personnel and speed-multiple claims we could not confirm, and a reference to a Kompozy plan that is no longer sold. Kompozy plan and product details come from kompozy.io and kompozy.io/pricing.
Sources
- Hugging Face — XiaomiMiMo/MiMo-V2.6-Pro-RL model card (MIT license) (read 2026-10-23)
- OpenRouter — Models API (Xiaomi MiMo-V2.6 Pro, Flash, Pro-UltraSpeed listings) (read 2026-10-23)
- Kompozy — Home (platforms, outputs per source, Persona Brief, review queue) (read 2026-10-23)
Related tools
- DeepSeek V4.1 Flash — DeepSeek's re-architected, natively multimodal Flash model — it reads images alongside text at V4-Flash pricing, and DeepSeek says it surpasses the larger V4-Pro on performance, cost, and speed.
- Qwen3.8-Omni-Flash — Alibaba's omni-modal understanding model, released September 18, 2026 — it reads text, images, audio, and video together in one request, holds a one-million-token context, and is tuned for cheap, agentic comprehension of long recordings.
- OpenRouter — A unified, OpenAI-compatible API that routes one endpoint to 400+ large language models from dozens of providers — with automatic fallback, cost and speed routing, and a single shared credit balance.