The honest Canto alternative (2026) for creators who need published content, not just accurate transcription
Canto is Wispr's accurate real-world speech model. Kompozy generates content and publishes every format across 9 platforms — an honest comparison.
Published 2026-09-17 · Updated
Short answer
Canto is Wispr's speech model for real-time dictation inside the Wispr Flow app, which is free, with Pro at $15 a month. On Wispr's own test of real dictations it had the lowest error rate of the models tested. It outputs text only. Kompozy is the alternative when your bottleneck is turning those words into published posts, video, and carousels.
Key takeaways
- Canto powers dictation in Wispr Flow; Wispr describes no standalone API.
- On a harder challenge set, Canto ranked second behind Gemini 3.1 Pro.
- For better transcription, compare Whisper, Deepgram, or AssemblyAI, not Kompozy.
- Kompozy takes pasted text and turns it into finished, scheduled content across formats.
If you searched "Canto alternative," it's worth being clear on what Canto is first, because it changes the answer. Canto is Wispr's speech-recognition model — the engine inside the Wispr Flow dictation app, detailed on September 17, 2026 — and it's built for one job: turning spoken audio into accurate text, even in the noisy, real-world conditions where most transcribers fall apart. At that job it's genuinely strong, and this page won't pretend otherwise.
I run Kompozy, and the honest framing is that Kompozy is not a more accurate speech model than Canto — it's a different category. If what you want is better transcription in noise, the real alternatives to Canto are other speech engines (OpenAI's Whisper, Deepgram, AssemblyAI, or the app it lives in, Wispr Flow), not Kompozy. But a lot of people typing "Canto alternative" aren't unhappy with the accuracy — they've realized transcription is only the input, and the thing they actually need is what happens to those words next: turned into posts, video, carousels, and a published schedule.
That's the honest reason this page exists. Canto turns your voice into clean text. Kompozy is a content generation and publishing engine: it takes an idea — including one you transcribed — and turns it into a full week of formats (clips, carousels, images, quote cards, blogs, newsletters, persona video, text posts), then schedules and publishes the set across nine platforms. If your bottleneck is distribution rather than transcription accuracy, that's the alternative you're really looking for.
Everything below was re-checked on 2026-10-23 against Wispr's Canto announcement and its pricing page, including company-reported benchmarks worth confirming independently; no invented weaknesses — its real-world accuracy is a genuine strength and I frame it as such.
What does Canto do?
Canto is Wispr's latest speech model for real-time dictation and the first model in a broader research program at its Advanced Interfaces Lab. It starts from a model pretrained on millions of hours of speech and text, and it powers dictation in the Wispr Flow app; Wispr's announcement does not describe a standalone API. Its design goal is accuracy in real-world dictation, and it takes specialized vocabulary from a user's dictionary so names and jargon come through. On Wispr's own test of 10 hours of real Flow dictations from more than 2,300 speakers, Canto had the lowest word error rate of the models tested, including models from Google, OpenAI, AssemblyAI, and Deepgram. On a harder challenge set with noise, music, traffic, wind, and whispered or far-field speech it ranked second behind Gemini 3.1 Pro, and it tied for the lowest error rate on LibriSpeech. What Canto does not do is anything downstream of the transcript: it doesn't generate video, images, or carousels, doesn't caption or reframe media per platform, doesn't write in a governed brand voice, and doesn't schedule or publish. Its output is accurate text — a fast, high-quality input another tool has to turn into finished content.
Why do people look for a Canto alternative?
People look past Canto as a content solution for one honest reason: it's a recognition model, and the content job has barely started when the transcript is done. A cleanly transcribed voice memo is raw material — a real content week needs that idea cut into a carousel, a quote card, an infographic, and a short-form video, captioned and reframed per platform, plus a scheduler that fans everything to every destination. None of that is Canto's job; it hands you text and you still have to design, cut, and upload everything by hand or across a stack of other tools. It's also tied to the Wispr Flow product rather than a general content workspace, and its headline benchmarks are the company's own. The alternative most creators actually want isn't a rival speech model — it's the engine that turns those transcribed words into published, on-brand content everywhere, and that also generates the video, images, and persona formats a transcriber can't. Kompozy is that engine, and it accepts a pasted transcript directly, so you keep Canto's accuracy and gain the entire second half of the workflow.
How do Canto and Kompozy compare feature by feature?
| Feature | Canto | Kompozy | Note |
|---|---|---|---|
| AI speech-to-text in noisy real-world audio | Yes — core strength | No | Canto's reason for existing: accurate transcription of real-world dictation, including noisy, low-volume, and far-field speech. Kompozy is not a speech model — it takes an idea (typed or transcribed elsewhere) and generates content from it. |
| Real-time dictation | Yes | No | Canto is built for live dictation via Wispr Flow; Kompozy has no dictation feature. |
| Contextual vocabulary (names / jargon) | Yes | Partial | Canto supplies context so terms transcribe correctly. Kompozy governs tone and banned words across generated copy via the Persona Brief — a different kind of "vocabulary" control. |
| Governed brand-voice copy generation | No | Yes | Canto reproduces what you said; Kompozy generates net-new captions, scripts, blogs, and newsletters held to one brand voice. |
| Persona / avatar video | No | Yes | Kompozy generates HeyGen-based Persona Shorts, Persona HeyGen, and Persona Frames with a face-locked identity; Canto generates no video. |
| Clip long-form video into shorts | No | Yes | Kompozy Clipped Shorts pulls captioned vertical cuts from a longer recording; Canto only transcribes audio. |
| Brand-exact carousels, quote cards, infographics | No | Yes | Kompozy renders pixel-exact multi-slide Carousels, Quote Graphics, and Infographic Photos via HyperFrames; Canto outputs text only. |
| Per-platform captioning & reframing (9:16 / 1:1 / 16:9) | No | Yes | Kompozy re-captions and reframes to each feed; Canto produces a transcript, not sized media. |
| Content repurposing into many formats | No | Cross-media | Canto gives you one block of text; Kompozy turns one source into video, image, text, blog, and newsletter formats. |
| Scheduling & autopilot | No | Yes | Kompozy has Autopilot plus a per-post review pipeline; Canto has no scheduler. |
| Direct publishing to social + blog + email | No | Yes | Eight social platforms plus blog and email from one queue; Canto publishes nothing. |
| Standalone availability | Partial — powers Wispr Flow | Yes — web app | Canto ships inside the Wispr Flow app, and Wispr's announcement describes no standalone API; Kompozy is a web-based content engine. |
How much do Canto and Kompozy cost?
| Tier | Canto plan | Canto price | Kompozy plan | Kompozy price |
|---|---|---|---|---|
| Entry | Wispr Flow Free (Canto) | $0 (Mac, Windows, iPhone, Android) | Kompozy Starter | $199/mo (5,500 credits) |
| Mid | Wispr Flow Pro | $15/user/mo (or $12 annual) | Kompozy Pro | $499/mo (18,000 credits) |
| Top | Wispr Enterprise | Custom, billed annually (SCIM, IT admin seats) | Kompozy Enterprise | Contact Sales |
What does Canto do well?
- Purpose-built for real-world dictation, and tested on audio with nearby speech, music, traffic, wind, and whispered or far-field speech, not just clean read-aloud text.
- On Wispr's test of 10 hours of real Flow dictations from 2,300+ speakers, Canto had the lowest word error rate of the models tested.
- Leads or ties the strongest transcribers on the company's own benchmarks, including a LibriSpeech tie.
- Real-time by design, and Wispr is already researching how to learn from user corrections in future models.
- Supports contextual vocabulary, so names and domain terms transcribe correctly.
- Ships inside a polished, cross-platform dictation app (Wispr Flow) rather than as raw infrastructure you have to wire up.
Where does Canto fall short?
- It's a recognition model — it produces clean text and nothing downstream: no video, images, carousels, or persona footage.
- No captioning or per-platform reframing; the output is text, not sized social media.
- No scheduler and no social publishing; you take the words elsewhere and distribute by hand.
- No cross-media repurposing — a transcript is one block of words, not a multi-format week.
- Tied to the Wispr Flow product, with no standalone API described at launch, and model pricing isn't broken out.
- Headline benchmarks are vendor-reported, so real-world accuracy is worth testing on your own voice and environment.
When should you pick Canto?
- Your bottleneck is transcription accuracy in noise. Canto is built exactly for messy, real-world audio, and Kompozy is not a speech model — it doesn't try to replace it.
- You need real-time dictation on the go. Delivered through Wispr Flow, Canto turns speech into clean text live in the places you actually record — a job Kompozy doesn't do at all.
- You just need a better speech-to-text engine. If the goal is transcription quality, the honest alternatives to Canto are other speech models like Whisper, Deepgram, or AssemblyAI, not a content engine.
When should you pick Kompozy instead?
- Your bottleneck is publishing a week, not transcribing words. Kompozy generates, captions, reframes, brands, and publishes across nine platforms — the entire second half a speech model doesn't touch.
- You need video and images from one idea. Kompozy makes Persona Shorts, Clipped Shorts, Carousels, Quote Graphics, and Infographics; Canto makes text only.
- You want one governed brand voice across every format. The Persona Brief holds tone and banned words across captions, scripts, blogs, and newsletters — Canto just transcribes what you say.
- You want transcribed ideas turned into finished, scheduled posts. Paste Canto's output into Kompozy and Autopilot carries it from words to a published multi-format calendar.
Can you use Canto and Kompozy together?
Here's the honest split. Canto is a speech-recognition model, and if your problem is that transcription falls apart in noise, it's a real advance — Kompozy doesn't try to out-transcribe it and won't pretend to. But content isn't measured in words captured; it's measured in posts shipped, across formats, every day. That's a different machine, and it's the one Kompozy is.
The two connect cleanly: capture your idea with Canto (via Wispr Flow), paste the transcript into Kompozy, and it becomes a brand-exact Carousel, Quote Graphics, an Infographic, native Text Posts, and a repackaged Email Newsletter — then, because it generates rather than just transcribes, it turns the same idea into a Persona Short or Persona Frames video with a face-locked identity, the media a speech model can't make.
Autopilot and a per-post review pipeline schedule and publish the whole package across the eight social platforms plus blog and email from a single queue, each post held to your Persona Brief.
Canto meters accurate words; Kompozy meters a full content channel produced and distributed. If you transcribe cleanly but keep hitting a wall at "now what do I do with this," that's the tell — start on Kompozy Starter at $199/mo, keep Canto for the fast, accurate capture, and let each do the job it's built for.
What does this look like in Kompozy?
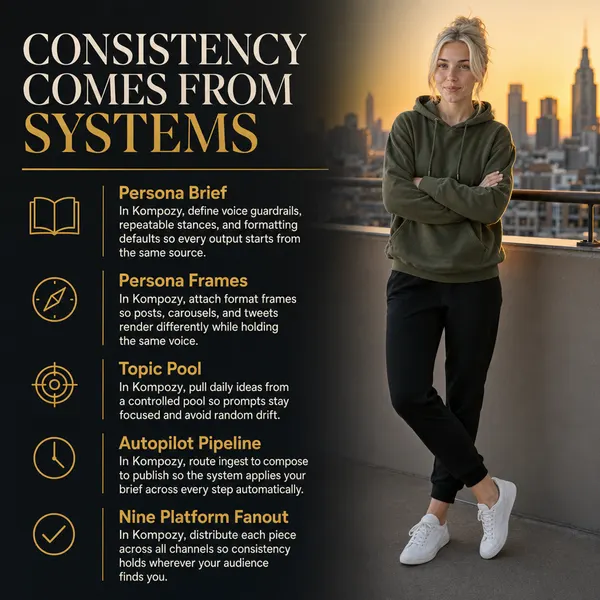
A persona infographic made in the Kompozy workspace from written ideas. Dictated text from Canto can be the starting point for a post like this.
Who is this for, and who should skip it?
Best for:
- Creators who dictate ideas and then struggle to turn them into posts
- Teams that want one governed voice across video, carousels, blogs, and newsletters
- Anyone who wants text turned into a scheduled multi-platform calendar
Not ideal for:
- Anyone whose problem is transcription accuracy (use Canto or another speech model)
- People who need live dictation in every app
- Users who want a free tool; Wispr Flow is free and Kompozy is paid
Frequently asked questions
Is Kompozy a replacement for Canto?
Not for transcription. Canto turns speech into accurate text, and Kompozy doesn't do that job — if you want better voice-to-text, keep Canto (via Wispr Flow) or pick another speech model. Kompozy replaces the step after: it turns an idea (including transcribed text you paste in) into carousels, video, quote cards, blogs, and scheduled posts across nine platforms, which Canto doesn't do.
Can Kompozy transcribe audio like Canto?
No. Kompozy is a content generation and publishing engine, not a speech-recognition model. The common workflow is to transcribe with Canto (or any speech-to-text tool), then paste the clean text into Kompozy, which generates and publishes finished multi-format content from it. They're complementary, not competing, for most creators.
What is the best Canto alternative?
It depends on what you actually want. For transcription itself, alternatives to Canto include OpenAI's Whisper, Deepgram, and AssemblyAI. For the thing transcription is a means to — published, multi-format content — the alternative is a content engine like Kompozy, which takes your transcribed words the rest of the way to posts, video, and a schedule.
How much does Canto cost versus Kompozy?
Canto ships inside Wispr Flow, which is free on Mac, Windows, iPhone, and Android, with Flow Pro at $15/user/month (or $12 billed annually) and custom Enterprise pricing; model-specific pricing isn't broken out. Kompozy starts at $199/mo (5,500 credits). The prices aren't directly comparable — Flow charges for dictation, Kompozy for generating and publishing content (to 4 platforms on Starter, 9 on Pro). Verify Flow's figures on wisprflow.ai/pricing.
Can I use Canto and Kompozy together?
Yes, and many creators do. Canto (via Wispr Flow) is a fast, accurate input layer: dictate a script, outline, or brain-dump even in noisy conditions, then paste the clean text into Kompozy, which generates the finished formats — Persona Shorts, carousels, quote cards, blogs, newsletters, text posts — and publishes them across the eight social platforms plus blog and email on Autopilot. You keep the accuracy of voice capture and add the entire publishing half.
How do we know this?
We checked every price, date, and feature claim about Canto and Wispr Flow on this page against the sources listed below on 2026-10-23 and corrected the ones that had changed. Kompozy plan details come from kompozy.io/pricing and kompozy.io/faq.
Sources
- Wispr — Canto: a speech model built for the real world (read 2026-10-23)
- Wispr Flow — Pricing (read 2026-10-23)
- Kompozy — Pricing (read 2026-10-23)
- Kompozy — FAQ (read 2026-10-23)
- AI Content Repurposing — The complete methodology for turning one source into 25-35 pieces of native-format content across every platform — without producing AI slop.
- Autonomous Content Creation — Most "autonomous" AI content is slop.
- AI Brand Voice & Persona — Without a Persona Brief, every AI output averages to the LLM default voice.